I wondered if...
AI was designed into the development lifecycle from the beginning. What would engineering delivery look like?
An attempt to build delivery tooling with AI in the workflow from the start — readiness scoring, role-based review agents and human-approved write-backs — with Azure DevOps kept as the system of record rather than replaced.
The Question
DeliveryIQ didn't begin with a product idea. It began with a series of questions that kept resurfacing as I experimented with AI-assisted development.
- If an engineering team is using AI-accelerated development tools, how does the rest of the delivery team keep pace?
- Could Scrum Bot, Code Bot and BA Bot. Three separate side projects I originally built to understand agent-based workflows—be combined into a single platform that was genuinely useful?
- What information would an AI actually need before it could confidently pick up a piece of work, plan it, implement it and test it without constantly asking for more context?
- Could software delivery itself be redesigned around AI, rather than simply adding AI to existing delivery tools?
It started with me tring to create better AI coding assistant, but ending up tring to understand what software delivery might look like if AI became another member of the engineering team.
The Problem
As I worked on personal projects and started adopting AI tooling (mainly Cursor) into my day-to-day work, I noticed something unexpected.
I found myself spending far less time thinking about how to implement something and much more time thinking about what I was trying to build, why it mattered and what assumptions I was making. I naturally started documenting ideas differently, capturing decisions, constraints and intent much earlier than I normally would.
The better that context became, the better the AI performed.
That immediately exposed a much larger problem.
Most software delivery processes aren't designed to preserve context. Requirements live in Azure DevOps or Jira. Architecture is documented somewhere else. Conversations happen in Teams or Slack. Design decisions are scattered across documents, and a surprising amount of knowledge exists only in the heads of the people who have worked on the system the longest.
As experienced engineers, we naturally join those dots together. We build up an understanding of the codebase over months or years, remember why certain decisions were made and instinctively know where to look when something doesn't quite make sense.
AI doesn't have that advantage.
It doesn't slowly build experience or intuition in the way a developer does. Every conversation starts from scratch, and it can only reason with the context it's been given.
Then I had one of those moments where you suddenly realise you've been looking at a familiar problem from a completely different angle.
I'd spent years in software development wondering why we needed so many refinement sessions, project kick-offs, design workshops and architecture meetings.
AI made the answer painfully obvious.
They're all trying to solve the same problem.
Context.
The difference is that we are incredibly good at filling in the gaps without even realising we're doing it. AI can't. Missing context can completly changes the decisions it makes.
The more I thought about it, the more I realised I was trying to solve a software delivery problem that AI had simply made impossible to ignore.
The Hypothesis
That eventually led me to a surprisingly simple hypothesis.
Software delivery should optimise for preserving context.
Most delivery platforms do an excellent job of helping teams organise work. They track tasks, estimate effort, manage backlogs and give everyone visibility of what's happening.
The part that interested me was everything that sits around those work items.
Why does this feature exist?
What assumptions have already been made?
Which architectural decisions have already been agreed?
What constraints does the implementation need to respect?
Those questions often have answers, but they're spread across documents, conversations, meeting notes and people's experience. As engineers we naturally piece that information together as we work. AI only sees what we explicitly give it.
That made me wonder if the delivery process itself could start somewhere completely different.
What if every project began by capturing everything known about the problem? The goals, assumptions, business context, technical constraints, design decisions and open questions. Almost like sitting down with a blank sheet of paper and writing out everything the team currently knows.
From there, AI could help organise that information into architecture documents, design decisions, epics, features and user stories, while keeping every artefact linked back to the original thinking that produced it.
By the time a work item reached implementation, it would already carry the context needed for someone to understand not only what needed building, but why it existed, the constraints it had to respect and the quality standards it needed to meet.
The technology will continue to evolve, but the need for engineers to understand intent, constraints and context isn't going away. If those things can remain connected from the first conversation through to the final commit, then both humans and AI have a much better foundation for making good engineering decisions.
That is what DeliveryIQ is really trying to explore.
DeliveryIQ is an experiment in whether software delivery can be redesigned around preserving context.
The Approach
The system centres on a single workflow. A work item syncs in from Azure DevOps together with its supporting Confluence documentation, and the planning agent attempts to produce an implementation plan from that combined context. The readiness score reflects how successfully it can plan the work and, more importantly, how many questions it has to ask before it can produce a sensible answer.
A deterministic gate sits after that assessment. Work below the threshold generates questions and recommendations, aimed at whoever can answer them. Work that passes can have implementation and test prompts generated, which a human then decides whether to apply back to Azure DevOps. The write-back is a button, not a background job, and it leaves an audit event behind.
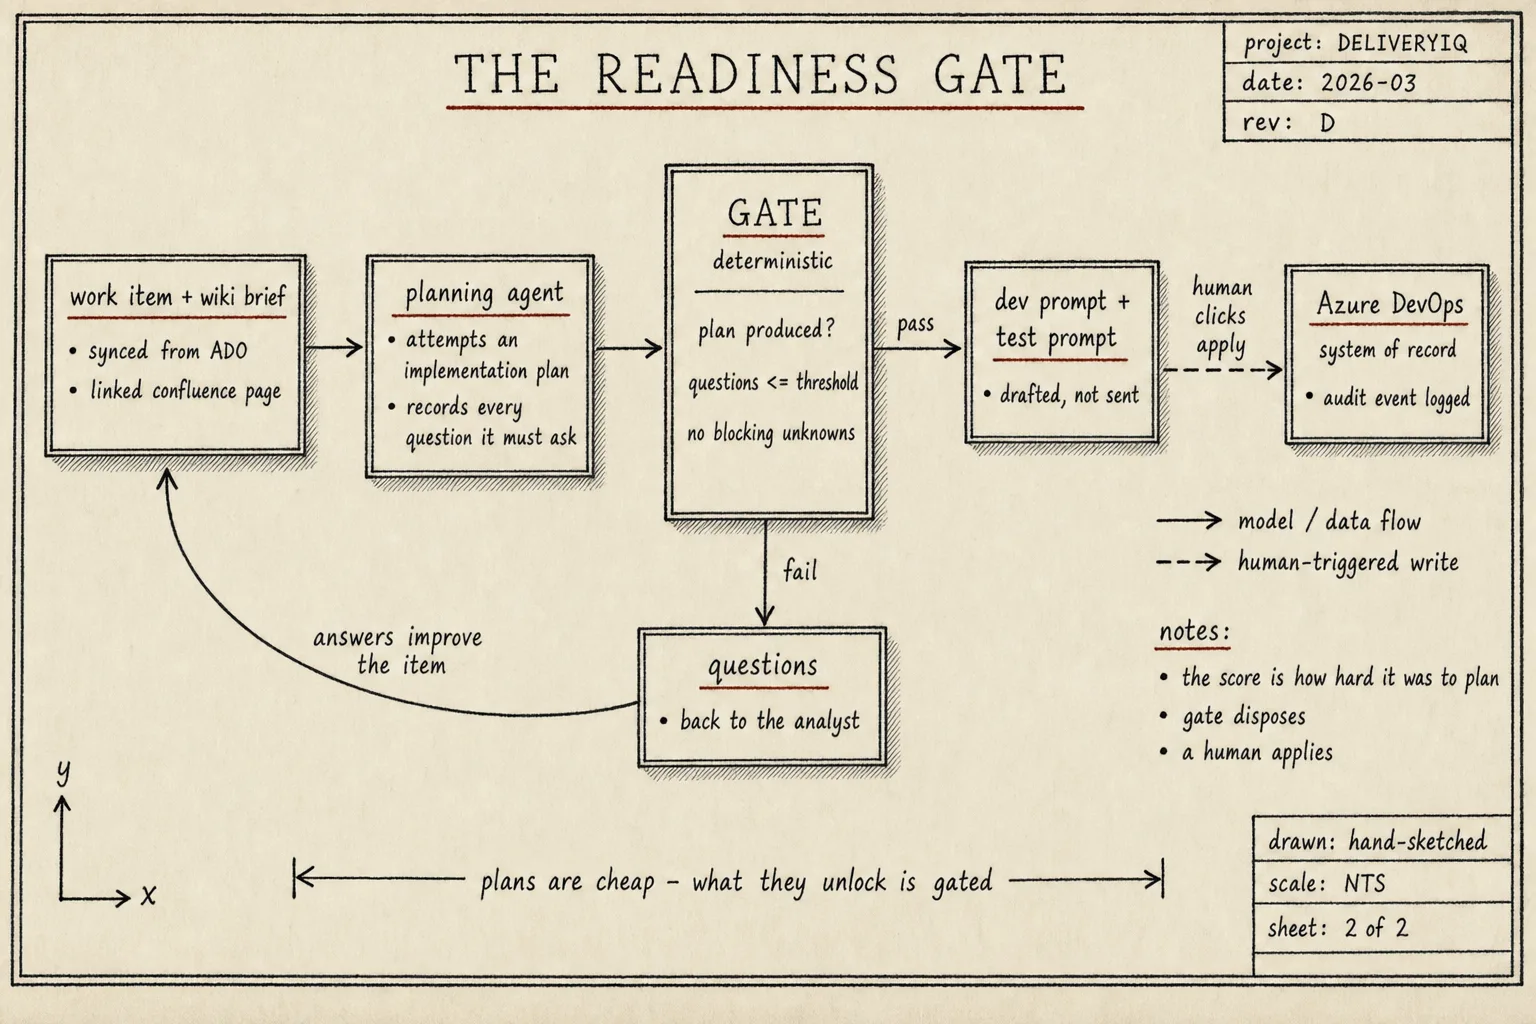
The whole workflow in one drawing. The model proposes, the gate disposes, and the only thing that writes to Azure DevOps is a human pressing a button.
Around that loop sit five review agents with single, narrow responsibilities — a tech lead, a non-functional-requirements specialist, a UX and product voice, a delivery manager and a designated sceptic — each reading the same work item from its own angle. Their purpose is not to rewrite requirements but to expose risks and missing information before implementation begins. The AI questions more than it writes, and the analyst keeps ownership of the words.
Architecture
A Next.js front end provides a view per delivery stage. A .NET 8 core API owns identity, persistence and the Azure DevOps and Confluence integrations. A Python FastAPI service does the AI work — analysis, retrieval and prompt generation — using Azure AI Foundry models. Supporting services include PostgreSQL with pgvector for operational and vector data, Redis for caching and RabbitMQ for messaging between the services. The AI service also exposes the platform's tools over the Model Context Protocol, so an external agent can work with the same delivery data the UI shows.
Model routing is not a fixed map of cheap-model-for-this, strong-model-for-that. It is a cost-weighted bandit: each model carries hand-written priors per task type, Thompson sampling picks a route, and feedback from completed tasks updates the posterior. Task classification deliberately never touches a model — it is cheap heuristics, on the grounds that spending inference to decide how to spend inference is the wrong shape.
Every scoring run is recorded with the model and provider that served it, a snapshot of the work item exactly as it was scored, and an audit event for anything applied back to Azure DevOps. When a score looks wrong, I can answer "what did it actually see?" — which is a different and better question than "why did it say that?"
Alongside the core runtime sits the experimental orchestration kernel, responsible for adaptive routing, planning and verification. It runs, but it currently exists as an optional execution path while the simpler direct workflow remains the primary implementation. That separation is deliberate: experimentation should not complicate the product's main workflow until it demonstrates clear value.
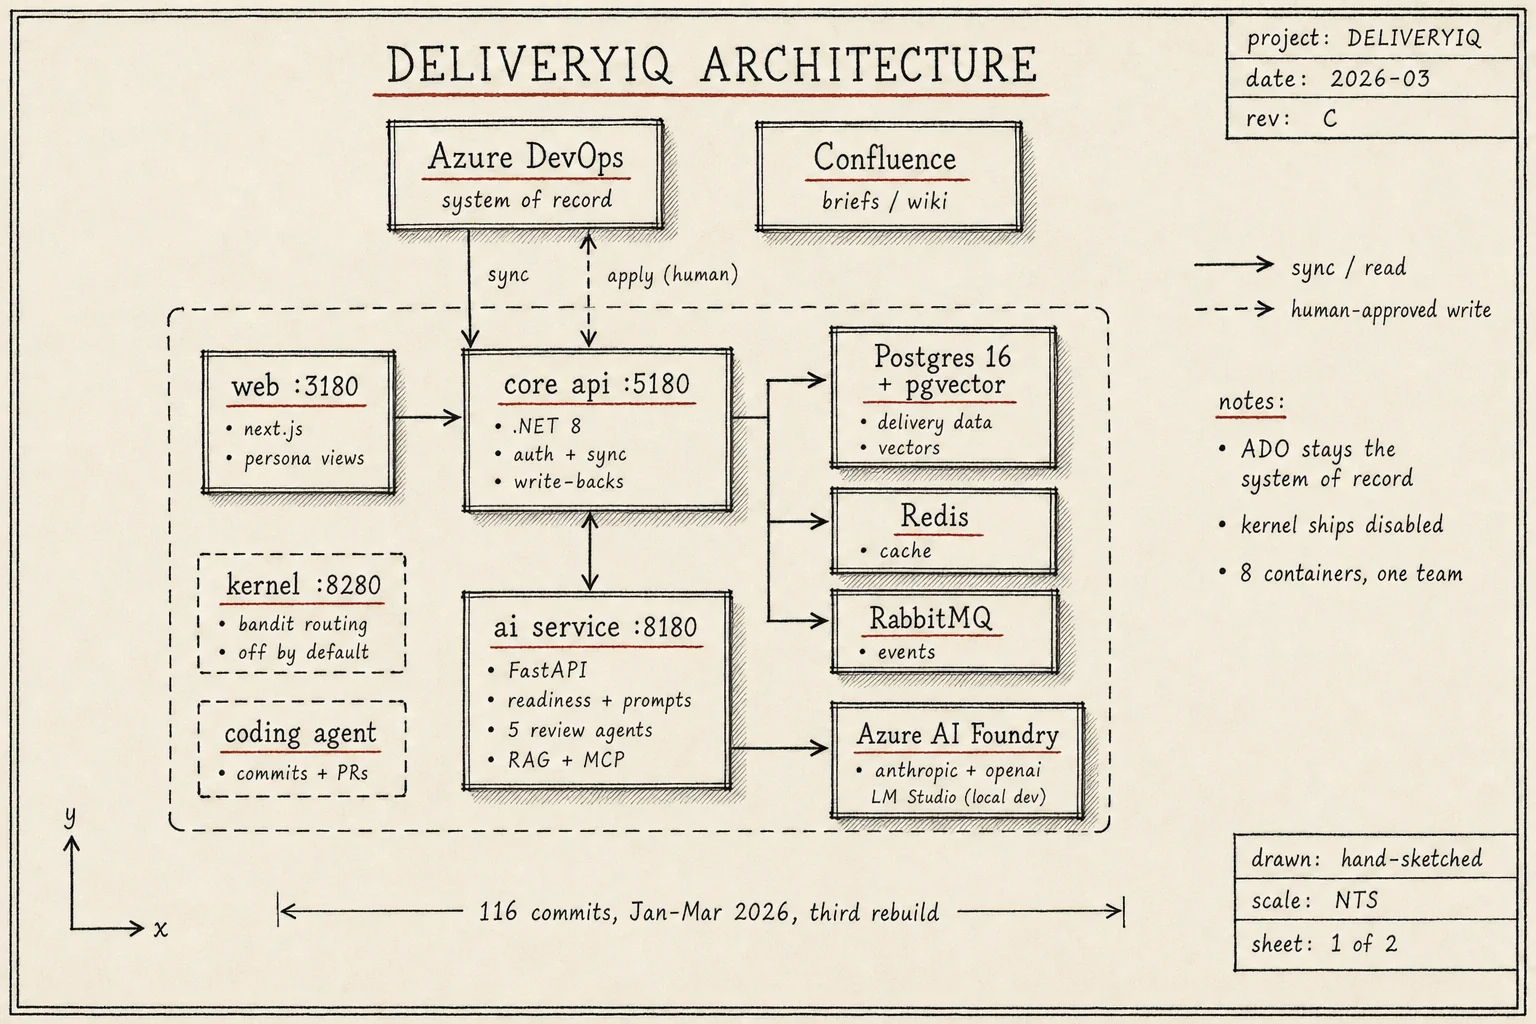
The current architecture. Azure DevOps sits outside the boundary on purpose — it is the system of record, and the platform holds synchronised copies rather than the truth. The dashed boxes are the parts still on trial.
Trade-offs
- Integrate rather than replace. Keeping Azure DevOps as the system of record costs real synchronisation code — snapshots, pending-push states, and a careful line between local edits and remote truth. What it buys is a tool a real team could adopt without migrating anything.
- AI judgement, deterministic policy. Models are good at interpreting ambiguous information and less suited to making operational decisions. DeliveryIQ uses AI for assessment and conventional software for enforcement.
- Questions over automation. Automatically rewriting requirements risks replacing missing information with plausible-looking text. Returning targeted questions keeps ownership with the analyst while still accelerating refinement.
- Research versus product. The orchestration kernel and coding agent explore more autonomous workflows, but the central hypothesis is about delivery readiness. Those components stay isolated until they justify their complexity — which means every flow has two code paths, one direct and one orchestrated, and I maintain both.
What Went Wrong
Quite a lot, actually.
Like most projects, DeliveryIQ turned out to be far bigger than I imagined when I started. Looking back, I massively underestimated how much work sits behind what sounds like a fairly simple idea.
"Create a readiness score."
That sounded easy enough. I could use a bit of machine learning, work out whether a work item is ready for development and away we go.
Then I asked the awkward question.
What does "ready" actually look like?
That's when reality arrived. To train anything useful I'd need hundreds, probably thousands, of real work items that had been manually reviewed and scored. Not just scored, but annotated with why they were good, why they weren't, what information was missing, what assumptions had been made and what caused problems later on.
I quickly realised I was no longer building AI model but signing myself up to become a full-time data curator and that suddenly didn't sound nearly as much fun.
The current approach is much simpler. Instead of trying to predict whether something is ready from historical data, I let the planning agent try to produce an implementation plan. The readiness score is then based on how successfully it can plan the work and, more importantly, how many questions it has to ask before it can produce a sensible answer.
It may not be not as clever as the original idea but it's also dramatically more practical.
The next lesson nearly gave me a heart attack.
At one point I'd connected DeliveryIQ to a real Confluence instance through MCP. I wanted to test against real documentation because, let's be honest, that's always far more interesting than toy examples.
While working in the Inception area I asked the AI to go through the project documentation, replace one term with another and remove references to an old concept.
What I meant was:
"Update the documents inside DeliveryIQ."
What the AI understood was:
"Update every document you can find."
Luckily I stream the model's reasoning while it's working. I watched it happily discover its new Confluence tool, explain that it had found the relevant documents... and then start searching the company wiki instead of my local project.
I've never disconnected a laptop from the network so quickly and to make things worse I happened to be in the office that day. Three other developers watched me suddenly close everything down and effectively pull the emergency stop on my laptop.
My Tech lead looked over and asked:
"Should we be worried?"
To be fair...
...probably.
Nothing was actually modified, but it taught me a lesson I'll probably never forget.
Never let agents anywhere near real systems until you've proved the safety rails.
The temptation to test against real data is incredibly strong because that's where all the interesting edge cases live.
It's also where you discover whether your safeguards actually work or not in my case.
Another surprise was repository search.
Initially I assumed exposing a repository through MCP would be enough. If the AI knew where every file lived, surely it could work everything else out.
It turns out that's only half the story.
Knowing where a file lives saves a bit of grep roulette but knowing how that file relates to the rest of the system is much more valuable.
That pushed me away from simple repository indexing and towards hybrid search using PostgreSQL and vector embeddings. Instead of only retrieving files that matched the words in the prompt, I could start retrieving code that was semantically related to the problem being solved.
Planning became noticeably better almost immediately.
That lesson ended up influencing Chronos as well. Once you start thinking about relationships between information rather than documents themselves, it changes how you approach search entirely.
Probably the biggest lesson from the whole project is that building AI features is actually the easy part.
Building systems that can trust those features, explain why they reached a conclusion and stop themselves doing something stupid... that's where the real engineering starts.
Lessons
-
Context is more valuable than code. The biggest bottleneck wasn't generating code—it was giving both humans and AI enough context to make good engineering decisions. Preserving intent throughout the delivery process turned out to be far more important than generating another user story.
-
Simple beats clever until you've proved the hypothesis. I started by thinking about machine learning models and predictive readiness scoring. In practice, letting the planning agent attempt the work and measuring how many questions it had to ask produced a far simpler system that is currently much more useful.
-
Building the dataset can be harder than building the AI. Before you can train or evaluate anything, you need to define what "good" actually looks like. Creating a high-quality labelled dataset quickly became a much bigger piece of work than building the models themselves.
-
Keep autonomous agents in a sandbox until you've proved the safety rails. Watching an AI happily prepare to update a company's Confluence instance was all the reminder I needed that powerful tools need strong boundaries. Real data is invaluable for testing, but only once the guard rails are in place.
-
Knowing where the code is isn't enough. Exposing a repository through MCP saved a bit of grep roulette, but combining repository indexing with vector search and semantic relationships dramatically improved planning and retrieval. Understanding how parts of the system relate to each other matters more than simply finding files.
-
Extend existing delivery tools rather than replacing them. Every version of DeliveryIQ that tried to become the system of record produced a better demo but a less practical product. Working alongside Azure DevOps instead of replacing it made the platform much easier to adopt.
-
AI should provide judgement, not authority. The most useful agents weren't the ones writing requirements—they were the ones asking difficult questions. AI is very good at identifying gaps and inconsistencies. Humans should still own the decisions.
-
Trust comes from transparency. Every AI decision should be explainable. Recording exactly what the model saw, how it reached a conclusion and what was written back makes debugging and challenging AI decisions significantly easier.
-
Feature flags are honest. If a component ships disabled for months, it's usually telling you something. My orchestration kernel is architecturally interesting, but until it demonstrates clear value it's an experiment, not a core part of the product.
-
Follow the evidence, even when it proves your original idea wrong. Several parts of DeliveryIQ ended up being completely different to what I originally planned. Some of the ideas I was most excited about turned out not to matter, while simpler approaches consistently produced better results. That's exactly why I build prototypes in the first place.
Current State
DeliveryIQ is a working prototype, not a product. The current repository is the third rebuild of the idea. It runs locally end to end: synchronisation, readiness scoring, the quality gate, prompt generation, the review agents and the write-back flows all work. The kernel and the coding agent run but are not yet trusted with the product's spine.
What does not exist is the measurement. The platform demonstrates that AI-assisted delivery workflows can be built; whether teams using readiness gates see fewer interruptions, less rework and more predictable delivery than conventional refinement is the claim the whole system is built on, and it is still untested. The repository is private because it is shaped around a real team's workflow, but I am happy to walk through the architecture and the code.
Next Questions
- What is the smallest honest evaluation of the core claim — do items that pass the gate get interrupted mid-sprint less than items that were started anyway?
- Which review agents consistently provide unique value?
- The kernel needs a decision: switch the spine onto it or delete it. Which?
- What evidence best predicts whether work is genuinely ready?
- Where should the boundary sit between AI assistance and delivery automation?